
Pull to refresh
Logo
Amazon adds a shared cache tier for self-hosted AI inference

Amazon adds a shared cache tier for self-hosted AI inference

New Capabilities

ElastiCache for Valkey now stores model state across GPU servers, which AWS measures at up to 40% lower cost and 80% lower first-token latency.

Overview

Updated 43 minutes ago

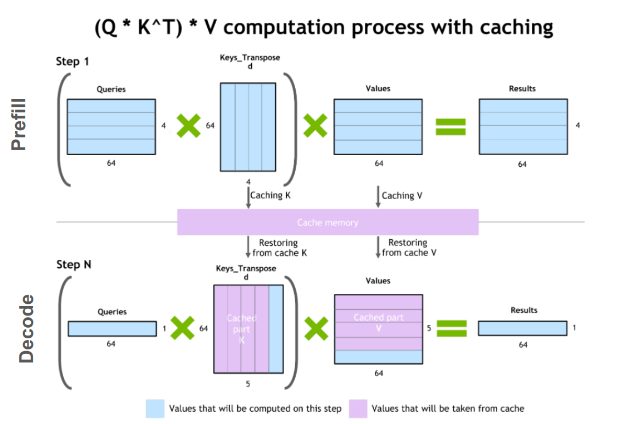
A long conversation with an AI model gets slower and more expensive the longer it runs, because the model re-reads the whole transcript before writing each new word. On a 100,000-token prompt, that re-reading takes tens of seconds. On November 18, 2026, Amazon Web Services began selling a way to skip it.

The product is a managed cache, built on ElastiCache for Valkey, that holds the model's intermediate state and lets any GPU server in the same data center reuse it. AWS measures up to 40% lower cost per million output tokens and up to 80% lower time to first token. Those are AWS's own benchmarks, not independent tests.

Why it matters

If shared caches become standard, the cost of a long AI conversation stops scaling with how many times it has been re-read.

Questions about this story

Free account needed to ask — your question is kept and asked for you right after sign-up. Answers are public.

No questions yet — be the first to ask.

Key Indicators

40%
Cost reduction per million output tokens
AWS's measured cut on a shared-document question-answering workload, after paying for the cache nodes.
80%
Reduction in time to first token
The delay before a model starts answering, measured against the same workload without the shared cache.
1.98x
Peak throughput per GPU server
Tokens per second at peak, compared with the same servers running without the shared cache.
13
AWS regions at launch
Availability spans the United States, Europe, and Asia Pacific.
95%
Share of coding-agent prompt tokens already seen
From third-party traces AWS cites: most of a coding agent's prompt is a prefix the model has processed before.
220 Gbps
Cache throughput per node
Data moved between GPU hosts and cache nodes over remote direct memory access, bypassing the operating system's network stack.

Voices

Curated perspectives — historical figures and your fellow readers.

Sign up to generate historical perspectives on this story.

Organizations Involved

Timeline

October 2025 November 2026

2 events Latest: Yesterday
  1. AWS launches distributed KV caching on ElastiCache for Valkey

    Latest Product launch

    The service adds a shared cache tier on new cache.i8ge.48xlarge nodes, reached over remote direct memory access within a single availability zone. AWS reports up to 40% lower cost and 80% lower first-token latency.

  2. LMCache paper lays out off-GPU cache reuse

    Research

    Researchers describe a layer that stores model state outside GPU memory and shares it across requests and engines. The work becomes the connector AWS ships with.

Scenarios

1

AWS extends the shared cache beyond one availability zone

Possible Resolves by Q3 2027

Discussed by: AWS's launch materials, which scope the cache to a single availability zone and to new cache.i8ge.48xlarge nodes

The current design keeps cache nodes in the same availability zone as the GPUs and connects them over remote direct memory access, which holds latency down but caps how far the cache reaches. Crossing zones would need either cross-zone remote direct memory access or a different replication model. AWS has not said it plans either.

2

A second cloud ships a managed KV cache tier

Possible Resolves by End of 2027

Discussed by: No public commitment from Google Cloud or Microsoft Azure; the scenario rests on the pattern of managed cache services following each other within a year

Both clouds already sell managed Valkey or Redis services and rent GPUs by the hour. If shared caching becomes a line item inference customers ask for, matching it is a product decision rather than a research problem. Neither company has announced one.

3

ElastiCache Serverless gets distributed KV caching

Possible Resolves by Q2 2027

Discussed by: An AWS Japan benchmark write-up, which notes the feature is unavailable on ElastiCache Serverless

The launch runs only on provisioned cache.i8ge.48xlarge nodes, and the cluster's shard count cannot be changed after creation. Serverless would remove that sizing decision, but it would also remove the direct control over node placement that the low-latency path depends on.

Historical Context

3 moments from history that rhyme with this story — and how they unfolded.

1998-1999

Content delivery networks (1998)

Web servers in the late 1990s rebuilt and resent the same pages to every visitor. Akamai, founded in 1998 by MIT researchers, put copies of that content on servers closer to users so the origin machine did the work once.

Then

Sites cut origin load and page-load times without buying more servers.

Now

Caching at a shared tier became standard plumbing for the web, and the origin-versus-edge split shaped how content is priced.

Why this matters now

The same move: repeated work stops being repeated because a shared tier holds the result.

November 1995

On-package L2 cache (1995)

Intel's Pentium Pro put the processor's second-level cache in the same physical package as the chip, shortening the path to memory the chip had already read.

Then

Off-chip memory traffic fell and server performance rose.

Now

The level hierarchy, L1 then L2 then main memory, became the standard way to describe and build processors.

Why this matters now

AWS names its tiers L0, L1, and L2 for exactly this reason: each level trades speed for size.

March 2024

Redis relicenses and Valkey forks (2024)

Redis moved its code from a BSD license to source-available terms. AWS, Google Cloud, and other providers backed a fork called Valkey under the Linux Foundation rather than accept the new terms.

Then

Managed cache services, including ElastiCache, shifted to Valkey.

Now

Redis later restored an open-source license option, but the fork held.

Why this matters now

The engine under this launch is Valkey, which is why AWS's cache can add large-object support on its own schedule.

Sources

(6)